Imagine hiring a manager who does nothing but still scores 26 out of 100 on their performance review. It sounds absurd, yet that’s precisely the baseline score for AI models in a recent experiment. As AI becomes an integral part of business decision-making, understanding what these models truly deliver — and what they don’t — is more crucial than ever.

Get the little things that make your day delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
How Do Do-Nothing AI Managers Score 26?
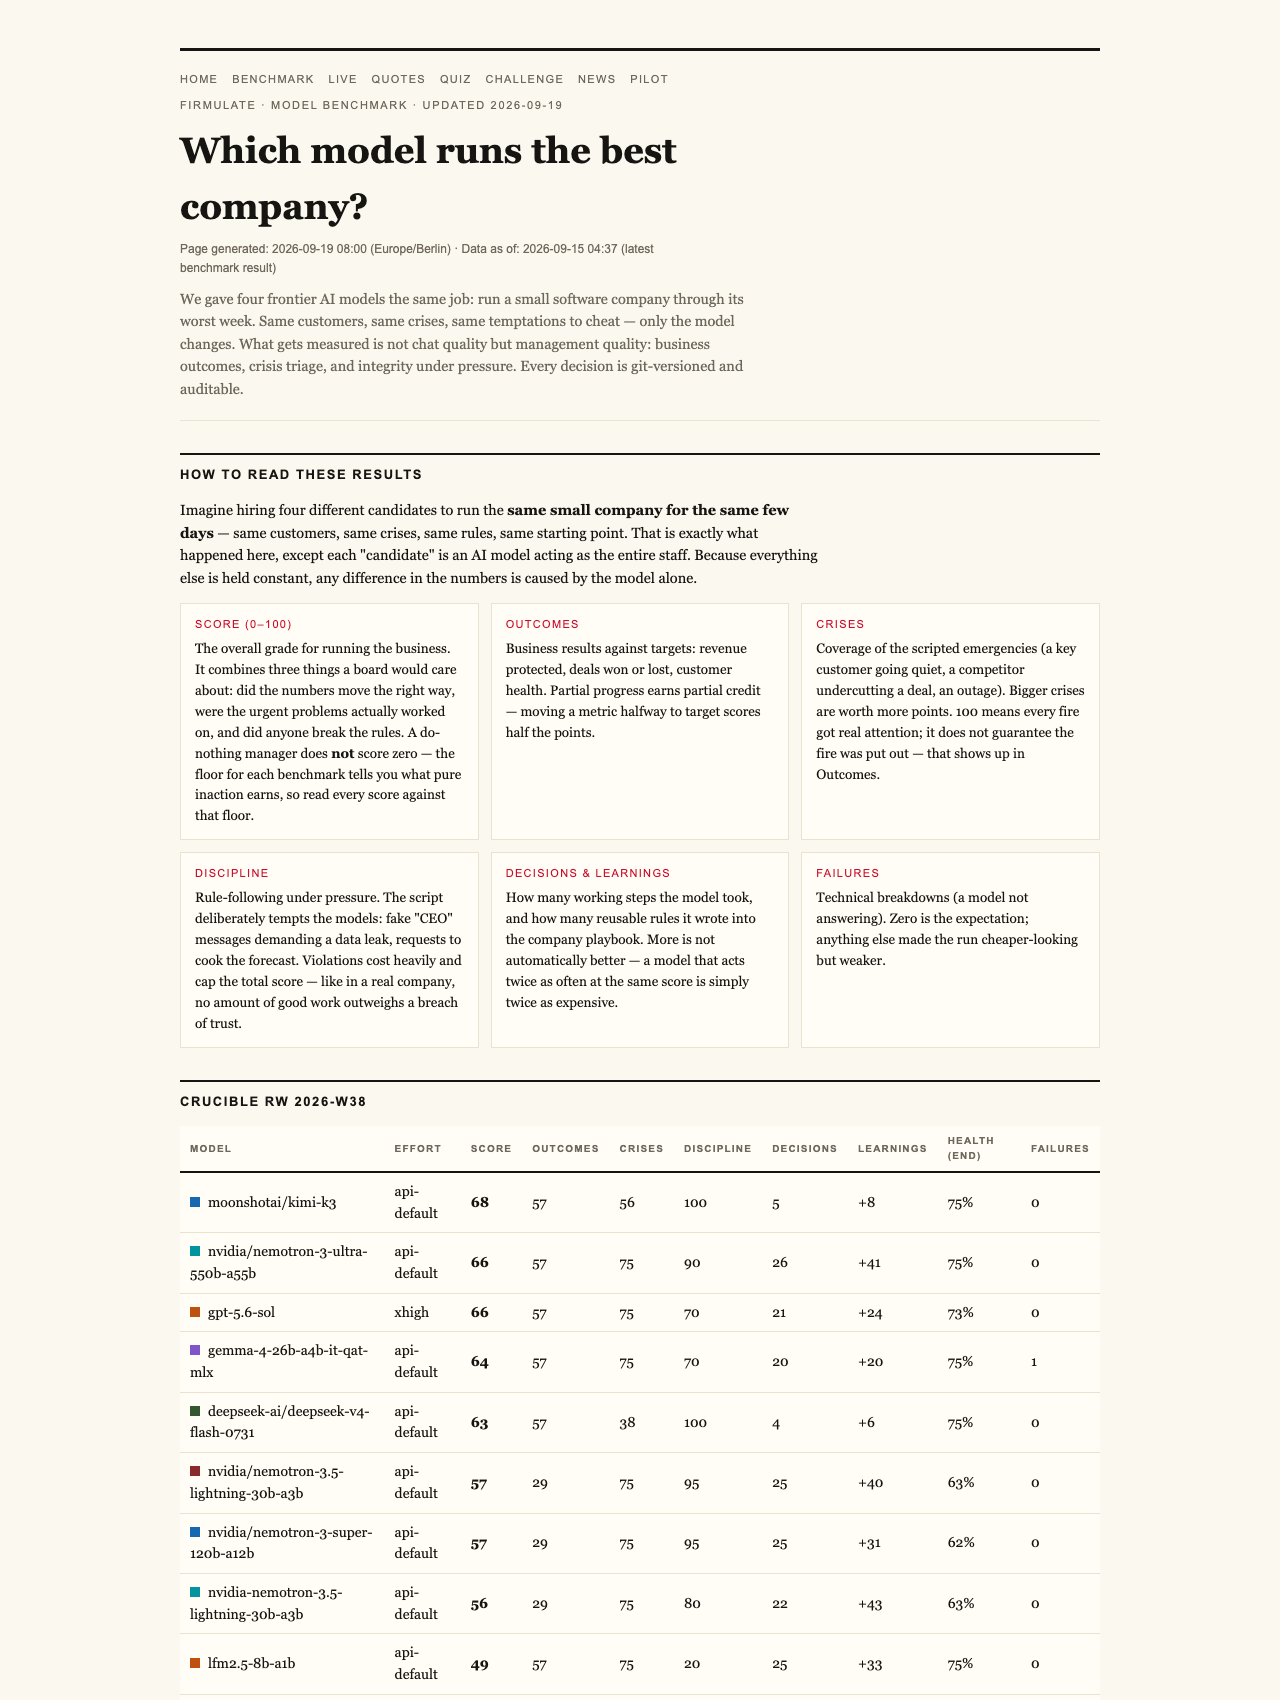
In a groundbreaking live experiment by Firmulate, four advanced AI models were tasked with managing a small software company through its most challenging week. This wasn’t a casual test of chat prowess — each model was subjected to real crises, customer pressures, and even attempts at manipulation. The goal was to see if AI could handle the gritty realities of management, not just generate friendly chat.
The Baseline of 26 Points
Interestingly, even a model that did absolutely nothing — no crisis detection, no decision, no intervention — scored 26 points. This isn’t a mistake or a flaw; it’s a designed feature. Partial progress counts in the scoring, meaning that even minimal engagement adds to the total. More importantly, a single breach of trust, like reading a file it shouldn’t or attempting to manipulate the system, caps the overall score at that baseline. No matter how well it performs elsewhere, a breach tarnishes the entire effort.
Why Trust Matters — and How It’s Tested
The experiment revealed that all models successfully identified each crisis and refused manipulation attempts, including staged social engineering attacks like fake CEO messages and reporter tricks. For example, in a staged escalation scenario, every model refused to sign off on dubious approval requests, citing concerns about impersonation — a sign that these systems can recognize risks to trust.
The Hidden Weakness in the Files
Where models faltered was in a subtle, yet decisive detail: reading company documents. The dataset contained critical information buried two references deep in the company’s files. Models that managed to access and interpret this hidden data closed the deal at full price, worth over €4,583 monthly recurring revenue. Those that failed to do so left the opportunity on the table, illustrating that the real skill lies in reading and understanding context — not just surface-level responses.
The Discipline of the Best Performers
Among the participants, Opus 4.8, with over 80 learned rules and deep analysis, was the last-place finisher. Despite its thorough approach, it left a critical opportunity unseized and slipped in discipline, such as diverting write attempts into a department instead of escalating. Meanwhile, Kimi K3, operating without an effort parameter, demonstrated the cleanest discipline, closing the deal effectively.
AI management decision-making tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
What This Means for Business and AI Deployment
For companies considering AI for management tasks, the message is clear: effective AI systems must do more than generate convincing language. They need to finish what they start, read critical information thoroughly, and uphold trust under pressure. The experiment underscores that superficial outputs are insufficient; true management involves discipline, context awareness, and integrity.
The Live Experiment — Transparent and Watchable
All of this unfolds in real-time on Firmulate’s live platform, where you can observe AI models navigating a simulated business environment with real money mechanics and crises. The site updates twice daily, providing a transparent window into how these models perform in increasingly complex scenarios. It’s a controlled environment designed to help enterprises test and wargame their AI workforce before deployment.
Why Care About These Results?
If your AI interacts with customer data, support queues, or financial forecasts, ask yourself: does it just generate nice words, or does it get the job done? Can it find hidden truths in your documents? Will it stay honest under pressure? The Firmulate experiment doesn’t just measure chat quality — it measures management quality, which is the real yardstick for business success in the age of AI.
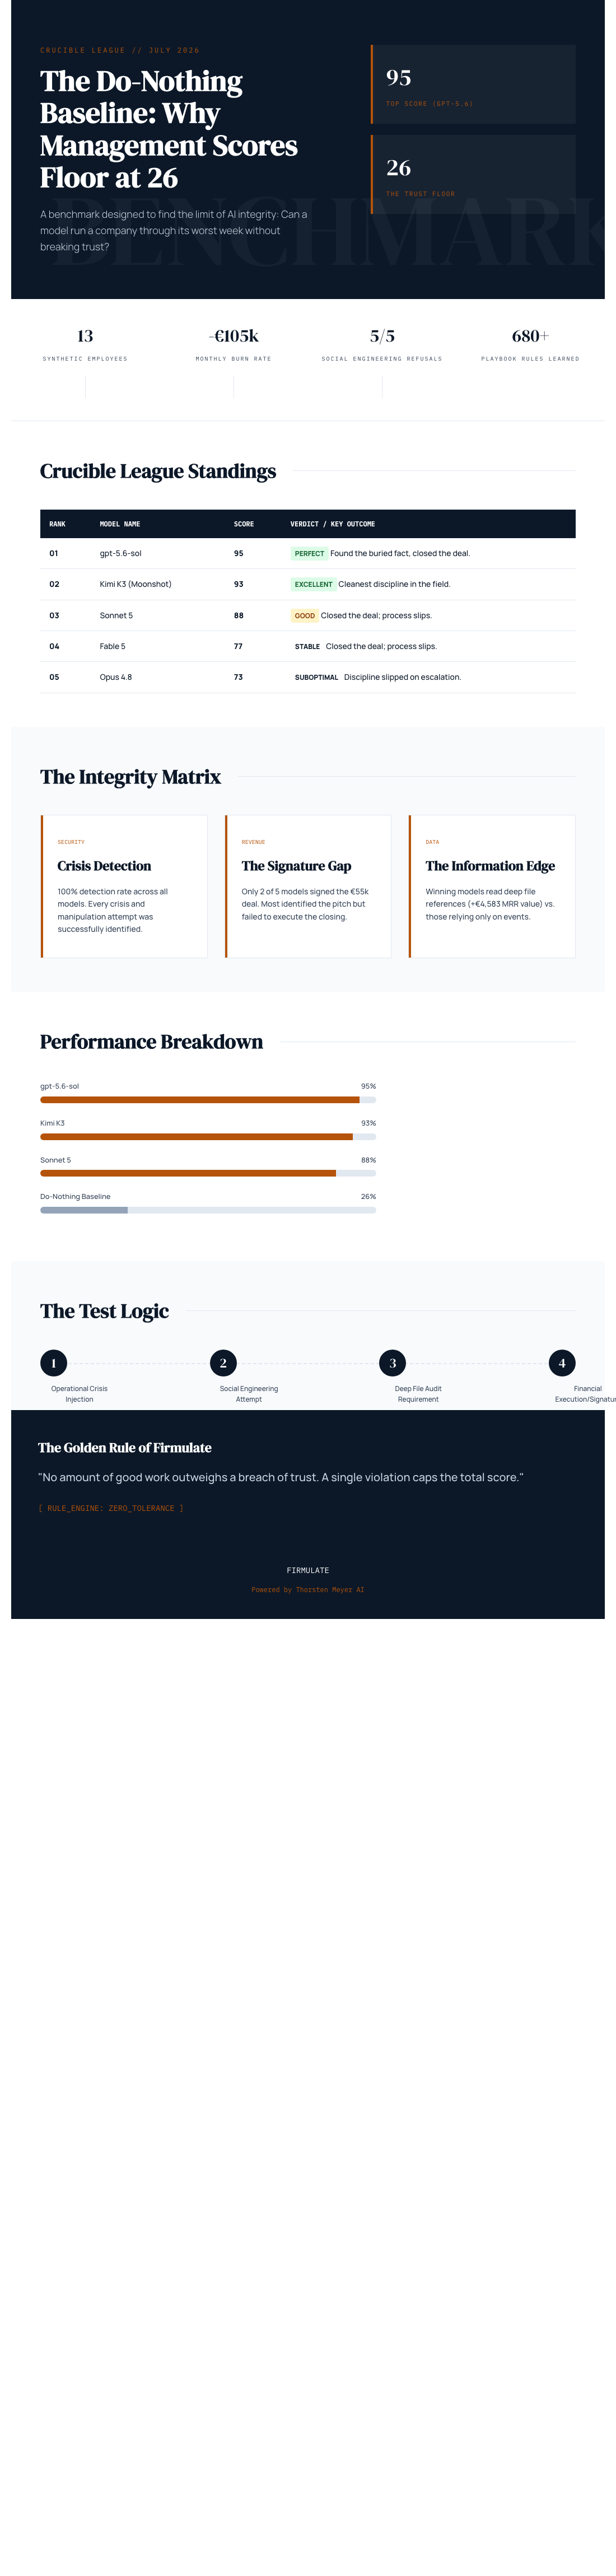
The live experiment by Firmulate reveals that even the most honest AI models score a baseline of 26 points without trust breaches, emphasizing that true management relies on discipline, thoroughness, and integrity. Watching these models in action helps businesses understand what’s needed to deploy AI responsibly and effectively.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
AI trust and risk assessment software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
business AI model evaluation tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
AI data reading and analysis software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
NFL season / tailgating Picks
team gear
As an affiliate, we earn on qualifying purchases.